
vidlizer
Point it at a video, image, or PDF — get structured JSON. uvx vidlizer[mcp]. Runs local (Ollama/gemma4, LM Studio, oMLX) or cloud (OpenRouter). CLI + MCP server for Claude Code, Cursor, and Claude Desktop.
Install / Use
claude mcp add arizawan -- npx -y github:arizawan/vidlizerIf the server publishes to npm under a different name, use that package instead — check the repo README.
MCP Server
Model Context Protocol server
Quality Score
Category
AI & Machine LearningSupported Platforms
Our assessment of vidlizer
vidlizer scores 78/100 on our quality scale, 416th of 585 AI & Machine Learning skills we index.
Its MCP Server is 29 KB long, well organised into 78 sections with 33 code examples: a thorough specification that gives an agent plenty to work with.
It has 3 GitHub stars, so there is little community track record yet; judge it on its content.
Maintenance, license and trust
- The repository was last updated about 5 months ago. That is recent enough to be usable, but agent tooling moves fast, so check the instructions against your agent's current version.
- Our last check on 2026-09-16 found the source still online.
- It is released under the MIT license, a permissive license that allows use, modification and commercial use with attribution.
- Its trust signals score 90/100, with 1 caution from licensing, adoption, age or documentation. These come from repository metadata, not a code audit — read the skill file before letting an agent act on it.
Safety scan
No issues foundOur scan of the first 100 KB of the file found no instruction hijacking, hidden characters, credential access, data exfiltration or destructive commands. An AI review of the same text found nothing harmful.
AI review by kimi-k2.7-code on 2026-09-25. Automated pattern scan on 2026-09-25. It catches known dangerous patterns, not every risk — read a skill before letting an agent act on it.
vidlizer compared with similar skills
All 4 of these similar skills score higher than vidlizer; compare them before choosing.
| Skill | Score | Stars | Updated | Format |
|---|---|---|---|---|
| vidlizer (this skill)by arizawan | 78 | 3 | 5mo ago | MCP Server |
| claude-memby thedotmack | 100 | 94.6k | today | CLAUDE.md |
| Agent-Reachby Panniantong | 100 | 85.3k | 9d ago | CLAUDE.md |
| Understand-Anythingby Egonex-AI | 100 | 84.1k | 13d ago | CLAUDE.md |
| headroomby headroomlabs-ai | 100 | 73.7k | today | CLAUDE.md |
Frequently asked questions
- How do I install vidlizer?
- Run
claude mcp add arizawan -- npx -y github:arizawan/vidlizer. The install tabs above show the steps for each supported agent. - Which AI agents does vidlizer work with?
- It is written for Claude Code, Claude Desktop and Cursor, as a MCP Server file. Other agents that read the same format can often use it too.
- Is vidlizer safe to use?
- Our scan of the first 100 KB of the file found no instruction hijacking, hidden characters, credential access, data exfiltration or destructive commands. An AI review of the same text found nothing harmful. It is MIT-licensed and scores 90/100 on trust signals. Skills are instructions an agent will follow, so read the file before installing it and do not approve commands you do not understand.
- Is vidlizer still maintained?
- The repository was last updated about 5 months ago. That is recent enough to be usable, but agent tooling moves fast, so check the instructions against your agent's current version.
Skill content
View source on GitHubvidlizer
Point it at a video, image, or PDF. Get structured JSON — scene by scene.


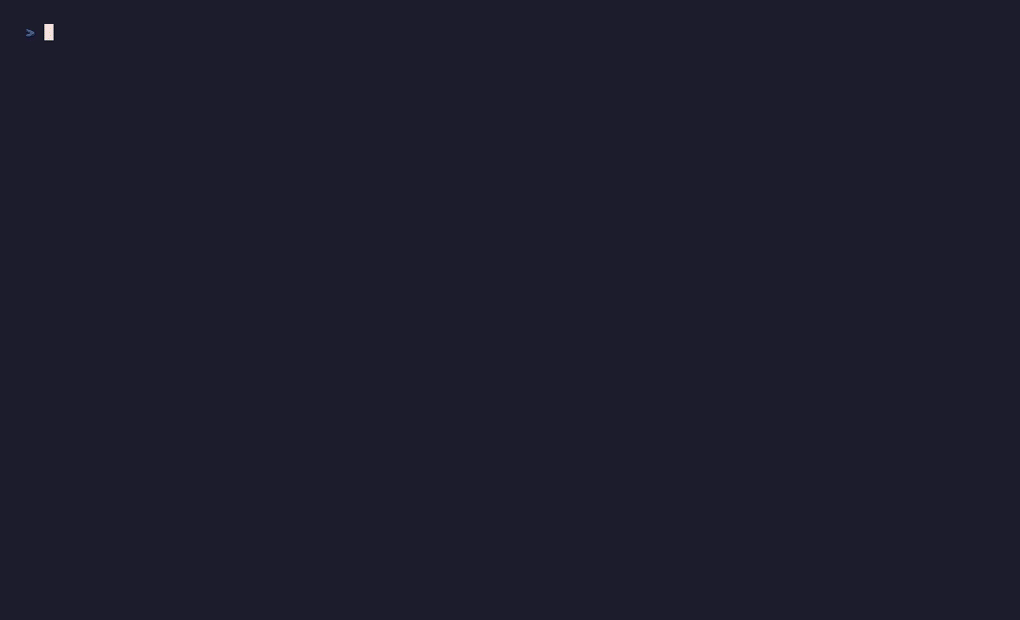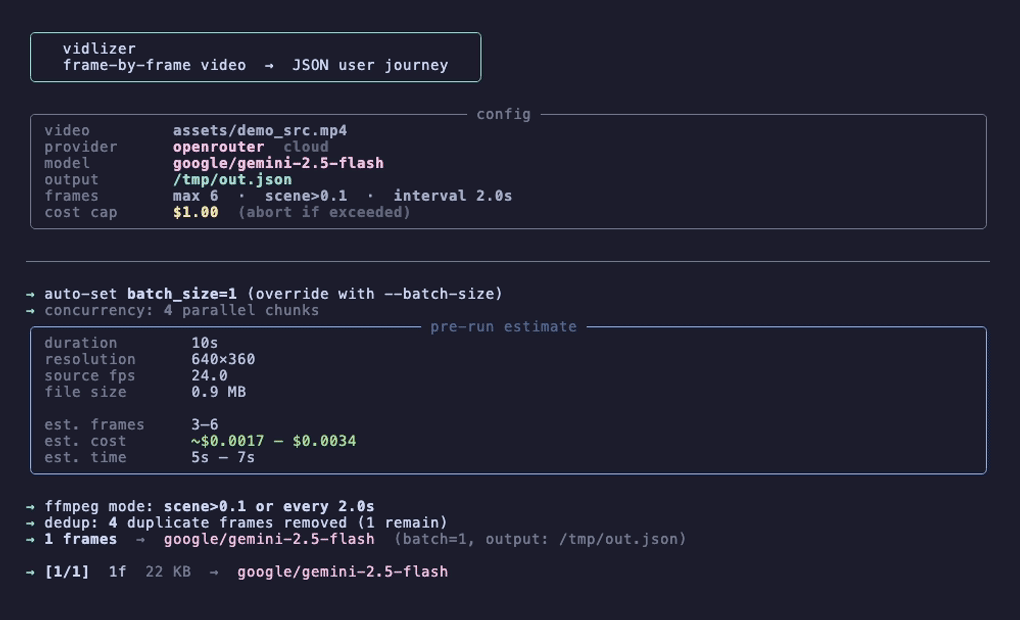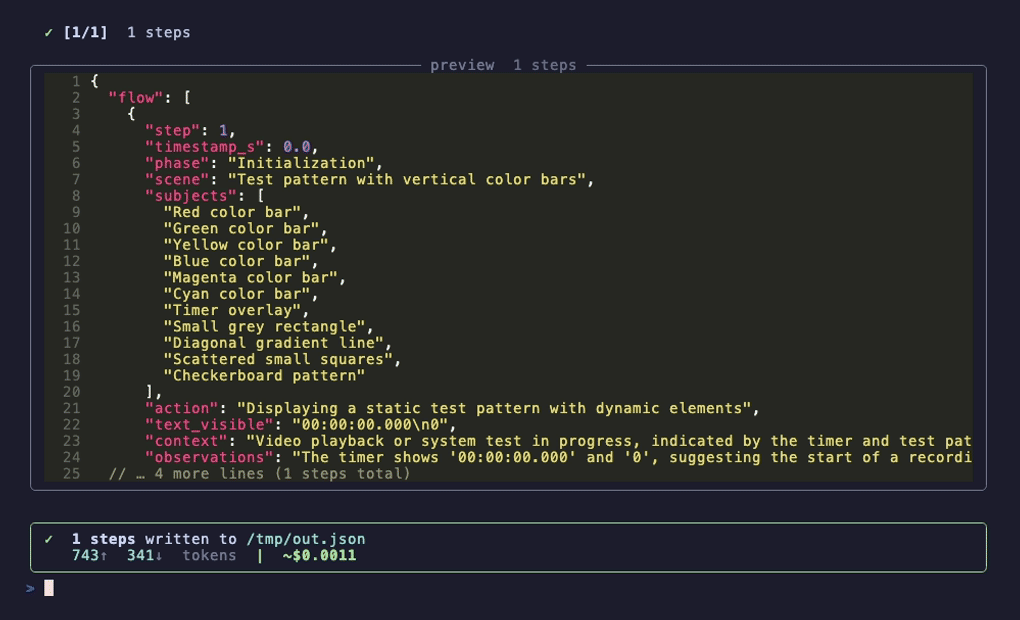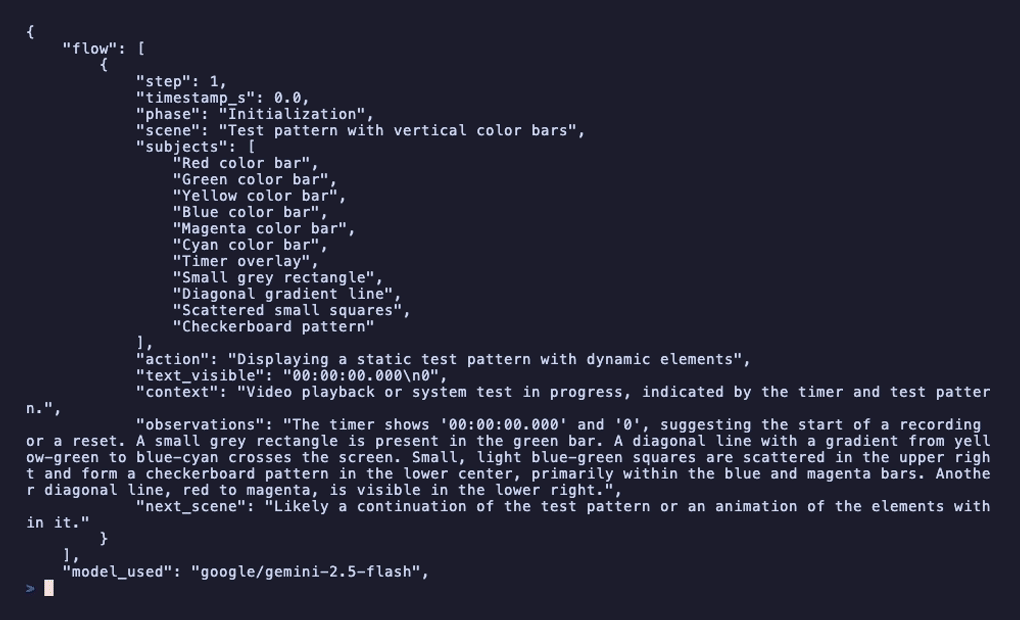
vidlizer pulls frames out of any video, image, or PDF using ffmpeg, sends them to a vision LLM, and returns a flow array — one entry per scene. Each entry tells you what happened, who was on screen, what text was visible, and what changed. If the video has audio, it transcribes it with Apple MLX Whisper and merges the speech into each step.
Runs fully local via Ollama or any OpenAI-compatible server (LM Studio, vLLM, oMLX) — no API key, no data leaving your machine. Or connect OpenRouter for cloud models. vidlizer setup detects what you have installed and writes your config in under a minute.
vidlizer demo.mp4
vidlizer "https://youtube.com/watch?v=..."
vidlizer screenshot.png
vidlizer document.pdf
✨ Features
- Any input — local video, image (jpg/png/webp/…), PDF, or URL (YouTube, Loom, Vimeo, Twitter)
- 4 providers — Ollama (fully offline), LM Studio (port 1234), oMLX (Apple Silicon, port 8000), OpenRouter (cloud) — auto-detected in that order
- Cross-provider fallback — primary model fails → automatically switches provider (e.g. oMLX → OpenRouter)
- JSON repair — malformed model output is re-sent to the model to fix before skipping; recovers from partial JSON
- Free-model guard —
:freeOpenRouter models auto-forceconcurrency=1to stay within rate limits - 3 output formats —
--format json(default),summary(plain text by phase),markdown(step-per-section doc) - Usage tracking —
--statsshows per-model token + cost breakdown across all runs;get_usage_stats()MCP tool - Auto transcript — detects audio, transcribes with Apple MLX Whisper (Neural Engine), merges speech into each flow step
- Perceptual dedup — removes near-duplicate frames before sending (saves tokens)
- analyze_moment —
--start/--endflags to focus on a time range - In-memory cache — repeat runs on the same file skip the API call
- Cost guard — aborts if spend exceeds
MAX_COST_USD(default $1.00) - Live progress — Rich streaming indicator shows elapsed time and token count per batch
- MCP server — use from Claude Code, Cursor, Claude Desktop; provider/model locked via env vars; result includes
model_used+provider_used - Auto-install — missing
ffmpegis brew-installed;mlx-whisperbundled in default install (macOS) doctor --fix— interactive repair wizard: installs missing ffmpeg/Ollama/LM Studio via Homebrew, re-runsvidlizer setupfor.env, upgrades mlx-whispermcp-setup— one-command MCP config wizard: detectsvidlizer-mcp, reads.env, writes editor config or shows aclaude mcp add-jsonone-liner- Mac-native — file picker dialog, Apple MLX transcription, handles macOS Unicode filenames (e.g. "11:26 AM")
📦 Requirements
- macOS (Apple Silicon recommended for transcription speed)
- Python 3.10+
- Ollama mode: Ollama installed + a vision model pulled (5 GB+ RAM)
- LM Studio mode: LM Studio 0.3.16+ with a vision model loaded
- Cloud mode: An OpenRouter API key
ffmpeg is installed automatically via Homebrew on first run if missing.
🚀 Install
Option 1 — uvx (no install, run directly)
uvx vidlizer setup
Option 2 — pipx (isolated, globally available)
pipx install vidlizer
vidlizer setup    # interactive wizard: detects providers, writes .env
Option 3 — pip / virtualenv
pip install vidlizer
vidlizer setup
Option 4 — from source
git clone https://github.com/arizawan/vidlizer.git
cd vidlizer
python -m venv .venv && source .venv/bin/activate
pip install -e .
vidlizer setup    # or: cp env.sample .env
First-run wizard
vidlizer setup detects all installed providers, lets you pick primary + fallback, and writes a .env for you. It also offers to pull a vision model for Ollama if none is installed.
$ vidlizer setup
  Detected providers:
    1.  Ollama        → qwen2.5vl:3b
    2.  OpenRouter    → google/gemma-3-27b-it:free

  Primary provider (1–2): 1
  Fallback (1–1, Enter to skip): 2

✓  .env written → /your/project/.env
Health check
vidlizer doctor          # shows ffmpeg, .env, provider, mlx-whisper status
vidlizer doctor --fix    # interactive repair: brew-installs ffmpeg/Ollama/LM Studio, re-runs setup
Manual provider setup
Ollama (fully offline, no API key):
# Install Ollama from https://ollama.com, then:
ollama pull qwen2.5vl:3b   # ~3.2 GB, requires 5 GB+ RAM (recommended)
ollama pull qwen2.5vl:7b   # ~6.0 GB, requires 10 GB+ RAM (best quality)
LM Studio (GPU-accelerated local inference):
# In LM Studio: load a vision model (e.g. Qwen2.5-VL 7B), enable the local server
# Set PROVIDER=openai and OPENAI_BASE_URL=http://localhost:1234/v1 in .env
OpenRouter (cloud):
# Paste your OpenRouter key in .env:
# OPENROUTER_API_KEY=sk-or-v1-...
⚡ Quick start
# Ollama — fully local, no API key
vidlizer demo.mp4 --provider ollama --model qwen2.5vl:3b

# LM Studio (or any OpenAI-compat server)
vidlizer demo.mp4 --provider openai --model qwen/qwen2.5-vl-7b-instruct

# OpenRouter (cloud)
vidlizer demo.mp4 --provider openrouter --model google/gemini-2.5-flash

# Analyze a YouTube video
vidlizer "https://www.youtube.com/watch?v=dQw4w9WgXcQ"

# Analyze a single image or PDF
vidlizer screenshot.png
vidlizer report.pdf

# Focus on a time range
vidlizer demo.mp4 --start 30 --end 90

# Output as Markdown or plain-text summary
vidlizer demo.mp4 --format markdown -o result.md
vidlizer demo.mp4 --format summary -o result.txt
Run with no arguments for an interactive file picker + provider/model selector.
📄 Output
Three formats via --format:
| Format | Flag | Default extension | Description |
|---|---|---|---|
| JSON | --format json | .analysis.json | Full structured flow array (default) |
| Markdown | --format markdown | .analysis.md | Step-per-section document with scene/action/speech |
| Summary | --format summary | .analysis.txt | Plain text grouped by phase |
Default output path is <normalized-name>.analysis.json (or matching extension), or pass -o path.
{
  "flow": [
    {
      "step": 1,
      "timestamp_s": 0.0,
      "phase": "Introduction",
      "scene": "Title card with product logo on dark background.",
      "subjects": ["Logo", "Text overlay"],
      "action": "Static title card displayed.",
      "text_visible": "vidlizer — analyze any video",
      "context": "Opening of a product demo.",
      "observations": "Clean minimal design.",
      "next_scene": "Screen recording of the CLI.",
      "speech": "Welcome to the vidlizer demo."
    }
  ],
  "transcript": [
    { "start": 0.0, "end": 2.4, "text": "Welcome to the vidlizer demo." }
  ],
  "model_used": "gemma-4-E2B-it-MLX-4bit",
  "provider_used": "openai"
}
model_used and provider_used reflect the model that actually produced the result — including after fallback. Surfaced in MCP analyze_video response so agents know which provider ran.
Flow step fields
| Field | Description |
|---|---|
| step | Sequential integer |
| timestamp_s | Approximate time in seconds (from frame label) |
| phase | Logical section — Introduction, Demo, Action, Conclusion… |
| scene | What is currently visible |
| subjects | Key people, objects, UI elements present |
| action | What is happening — interaction, movement, narration, event |
| text_visible | All readable text on screen |
| context | Persistent state — timer, score, topic, brand… |
| observations | Errors, anomalies, emotions, key facts |
| next_scene | Brief description of what follows |
| speech | Transcript text spoken during this step (audio videos only) |
🤖 Models
All providers send one frame per request (batch_size=1) for maximum compatibility with context-limited models. Thinking-mode output (<think> tags) is stripped automatically.
Local — Ollama
Fully offline, no API key. Install with ollama pull <name>:
| Model | Disk | RAM | Notes |
|---|---|---|---|
| qwen2.5vl:3b ★ | 3.2 GB | ~5 GB | Recommended — 128K ctx, strong JSON, multi-image |
| qwen2.5vl:7b ★ | 6.0 GB | ~9 GB | Best Ollama quality — 128K ctx, needs 10+ GB RAM |
| minicpm-v:8b | 5.5 GB | ~8 GB | Strong OCR + visual reasoning, 32K ctx |
| llava-onevision:7b | 5.5 GB | ~8 GB | Strong multi-image + video frames, reliable JSON |
Fallback order (if configured model unavailable): qwen2.5vl:7b → qwen2.5vl:3b → minicpm-v:8b → llava-onevision:7b → llava:13b → llava:7b
Uses Ollama's native /api/chat with format: json for reliable structured output.
Local — LM Studio / oMLX / vLLM / LocalAI (OpenAI-compatible)
GPU-accelerated inference via any OpenAI-compatible server. Set PROVIDER=openai and point OPENAI_BASE_URL at your server.
| Model | VRAM | Notes |
|---|---|---|
| qwen/qwen2.5-vl-7b-instruct ★ | ~8 GB | Recommended — 128K ctx, reliable JSON, multi-image |
| qwen/qwen3-vl-8b ★ | ~10 GB | Latest Qwen vision — thinking tags stripped automatically |
| qwen/qwen2.5-vl-3b-instruct | ~5 GB | Lightweight — fast, 5–6 GB VRAM |
| google/gemma-4-e4b-it | ~6 GB | Google MoE — LM Studio 0.3.16+ native support |
| google/gemma-4-9b-it | ~10 GB | Stronger Gemma 4 — 128K ctx, better instruction following |
| zai-org/glm-4.6v-flash | ~8 GB | ZhipuAI MoE — 128K ctx, strong JSON, low latency |
| openbmb/minicpm-v-4.5 | ~8 GB | 8B Qwen3-based — strong OCR, multi-image, vLLM ready |
oMLX (Apple Silicon native, omlx.ai) — MLX-format models from HuggingFace, auto-detected on port 8000 (distinct from LM Studio). Model IDs are HuggingFace paths:
| oMLX Model | Unified RAM | Notes |
|---|---|---|
| mlx-community/Qwen2.5-VL-7B-Instruct-8bit ★ | ~8 GB | Best Apple Silicon pick — fast, strong JSON |
| mlx-community/Qwen2.5-VL-3B-Instruct-8bit | ~4 GB | Lightweight — 4–5 GB RAM |
| mlx-community/Qwen3-VL-8B-8bit | ~9 GB | Latest Qwen vision — thinking tags stripped |
| mlx-community/MiniCPM-V-2_6-8bit | ~8 GB | Strong OCR + reasoning |
Model IDs are as shown in LM Studio's model browser, oMLX's admin panel, or your vLLM config. LM Studio / oMLX serve one model at a time (no fallback needed). vLLM with multiple models loaded uses the same fallback sequence.
Fallback fragment order (vLLM / oMLX with multiple models): qwen2.5-vl-7b → qwen2.5-vl-3b → qwen3-vl → gemma-4 → glm-4 → minicpm-v → llava-onevision → llava
Cloud — OpenRouter
Models fetched live with current pricing. Run vidlizer --list-models to see the live list.
| Model | Input / 1M tok
Truncated for display — read the full file on GitHub.
Related Skills
claude-mem
94.6kPersistent Context Across Sessions for Every Agent – Captures everything your agent does during sessions, compresses it with AI, and injects relevant context back into future sessions. Works with Claude Code, OpenClaw, Codex, Gemini, Hermes, Copilot, OpenCode + More
Agent-Reach
85.3kGive your AI agent eyes to see the entire internet. Read & search Twitter, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu — one CLI, zero API fees.
Understand-Anything
84.1kGraphs that teach > graphs that impress. Turn any code into an interactive knowledge graph you can explore, search, and ask questions about. Works with Claude Code, Codex, Cursor, Copilot, Gemini CLI, and more.
headroom
73.7kCompress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.

Languages
Trust signals
From repository metadata: license, adoption, age and documentation. Not a code audit — see the Safety scan above for what the skill file itself contains.