
IdeaGauntlet
⚔️ Stress-test your product and startup ideas before writing code. An adversarial AI tool for multi-role debate, synthetic user feedback, and validation planning.
Install / Use
claude mcp add Thuong180702 -- npx -y github:Thuong180702/IdeaGauntletIf the server publishes to npm under a different name, use that package instead — check the repo README.
MCP Server
Model Context Protocol server
Quality Score
Category
Content & MediaSupported Platforms
Our assessment of IdeaGauntlet
IdeaGauntlet scores 83/100 on our quality scale, 573rd of 866 Content & Media skills we index.
Its MCP Server is 27 KB long, well organised into 61 sections with 25 code examples: a thorough specification that gives an agent plenty to work with.
It has 3 GitHub stars, so there is little community track record yet; judge it on its content.
Maintenance, license and trust
- The repository was last updated 34 days ago, so IdeaGauntlet is actively maintained.
- Our last check on 2026-09-18 found the source still online.
- It is released under the MIT license, a permissive license that allows use, modification and commercial use with attribution.
- Its trust signals score 92/100, with 1 caution from licensing, adoption, age or documentation. These come from repository metadata, not a code audit — read the skill file before letting an agent act on it.
Safety scan
No issues foundOur scan of the whole file found no instruction hijacking, hidden characters, credential access, data exfiltration or destructive commands. An AI review of the same text found nothing harmful.
AI review by kimi-k2.7-code on 2026-09-24. Automated pattern scan on 2026-09-24. It catches known dangerous patterns, not every risk — read a skill before letting an agent act on it.
IdeaGauntlet compared with similar skills
All 4 of these similar skills score higher than IdeaGauntlet; compare them before choosing.
| Skill | Score | Stars | Updated | Format |
|---|---|---|---|---|
| IdeaGauntlet (this skill)by Thuong180702 | 83 | 3 | 34d ago | MCP Server |
| Agent-Reachby Panniantong | 100 | 86.2k | 14d ago | CLAUDE.md |
| headroomby headroomlabs-ai | 100 | 74.1k | today | CLAUDE.md |
| rufloby ruvnet | 100 | 73.5k | today | CLAUDE.md |
| CowAgentby zhayujie | 100 | 47.2k | today | CLAUDE.md |
Frequently asked questions
- How do I install IdeaGauntlet?
- Run
claude mcp add Thuong180702 -- npx -y github:Thuong180702/IdeaGauntlet. The install tabs above show the steps for each supported agent. - Which AI agents does IdeaGauntlet work with?
- It is written for Claude Code and Claude Desktop, as a MCP Server file. Other agents that read the same format can often use it too.
- Is IdeaGauntlet safe to use?
- Our scan of the whole file found no instruction hijacking, hidden characters, credential access, data exfiltration or destructive commands. An AI review of the same text found nothing harmful. It is MIT-licensed and scores 92/100 on trust signals. Skills are instructions an agent will follow, so read the file before installing it and do not approve commands you do not understand.
- Is IdeaGauntlet still maintained?
- The repository was last updated 34 days ago, so IdeaGauntlet is actively maintained.
Skill content
View source on GitHubIdeaGauntlet
Stress-test product ideas before you build them.
IdeaGauntlet is an open-source CLI and library that turns a raw product idea into adversarial critique, multi-role debate, synthetic user objections, validation plans, and idea comparison.
Built for founders, indie hackers, and product engineers who want sharper pre-validation before spending weeks building the wrong thing.
Most AI tools help you generate more ideas. IdeaGauntlet helps you survive the one you already have.


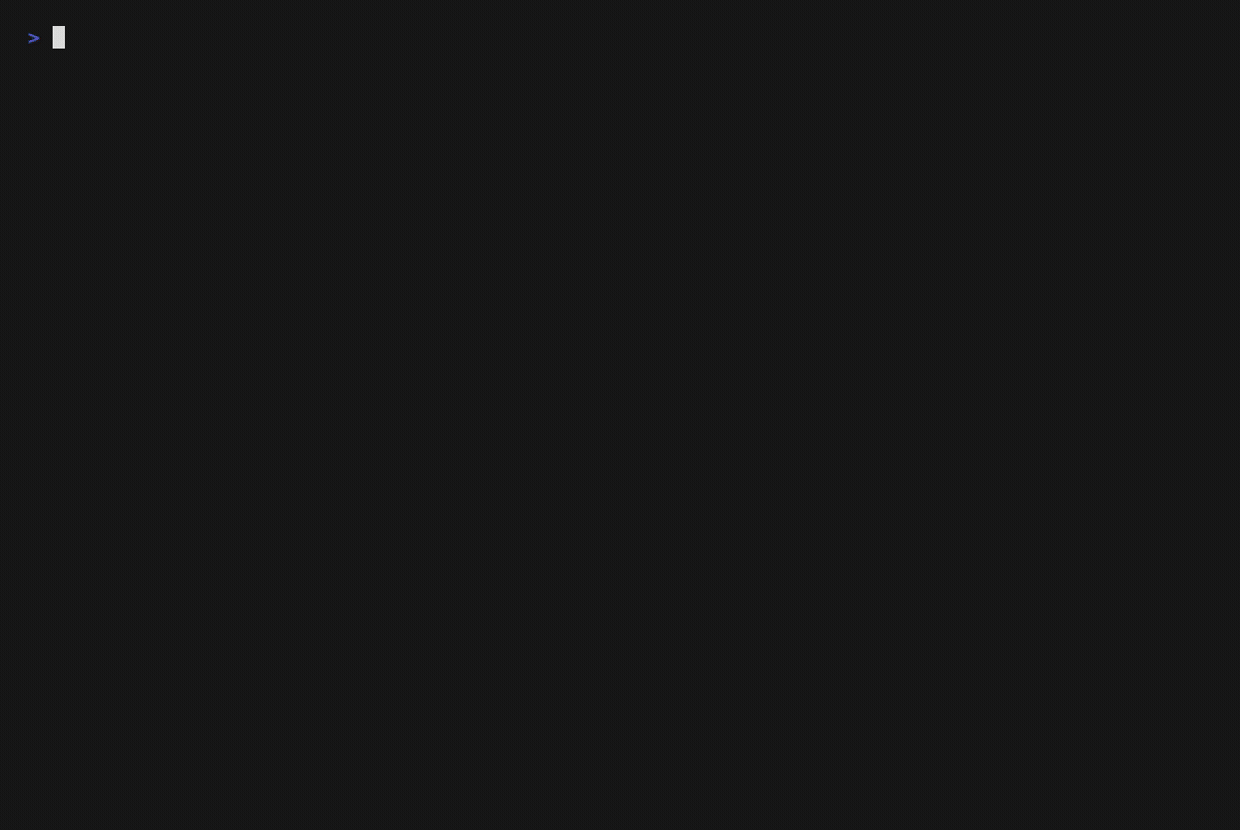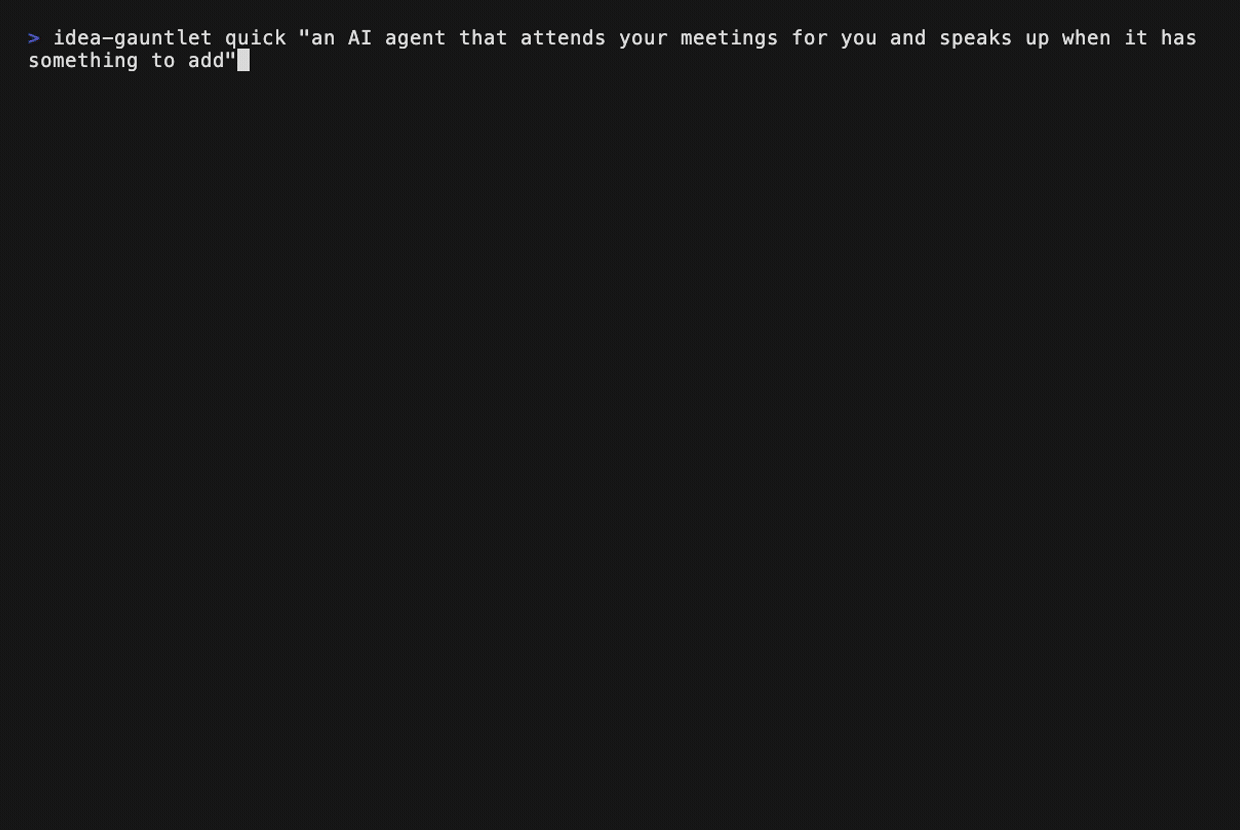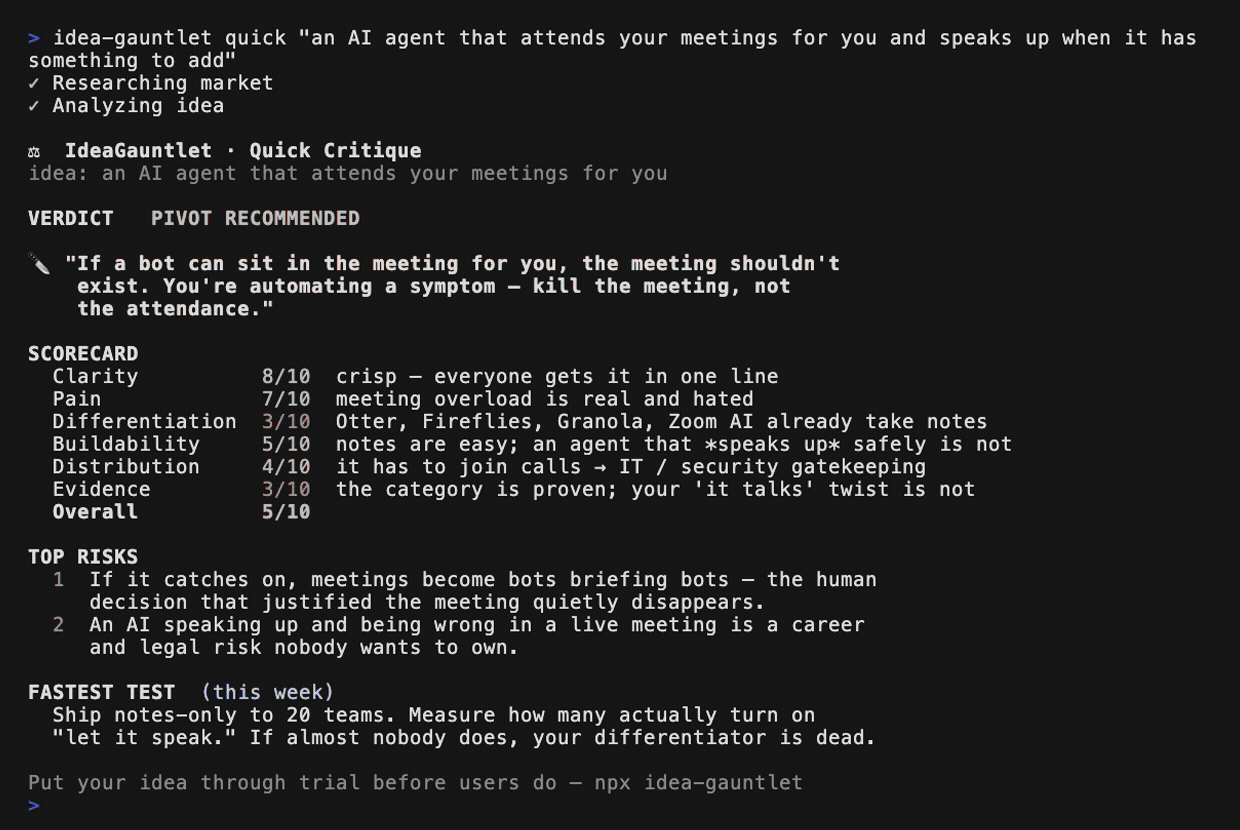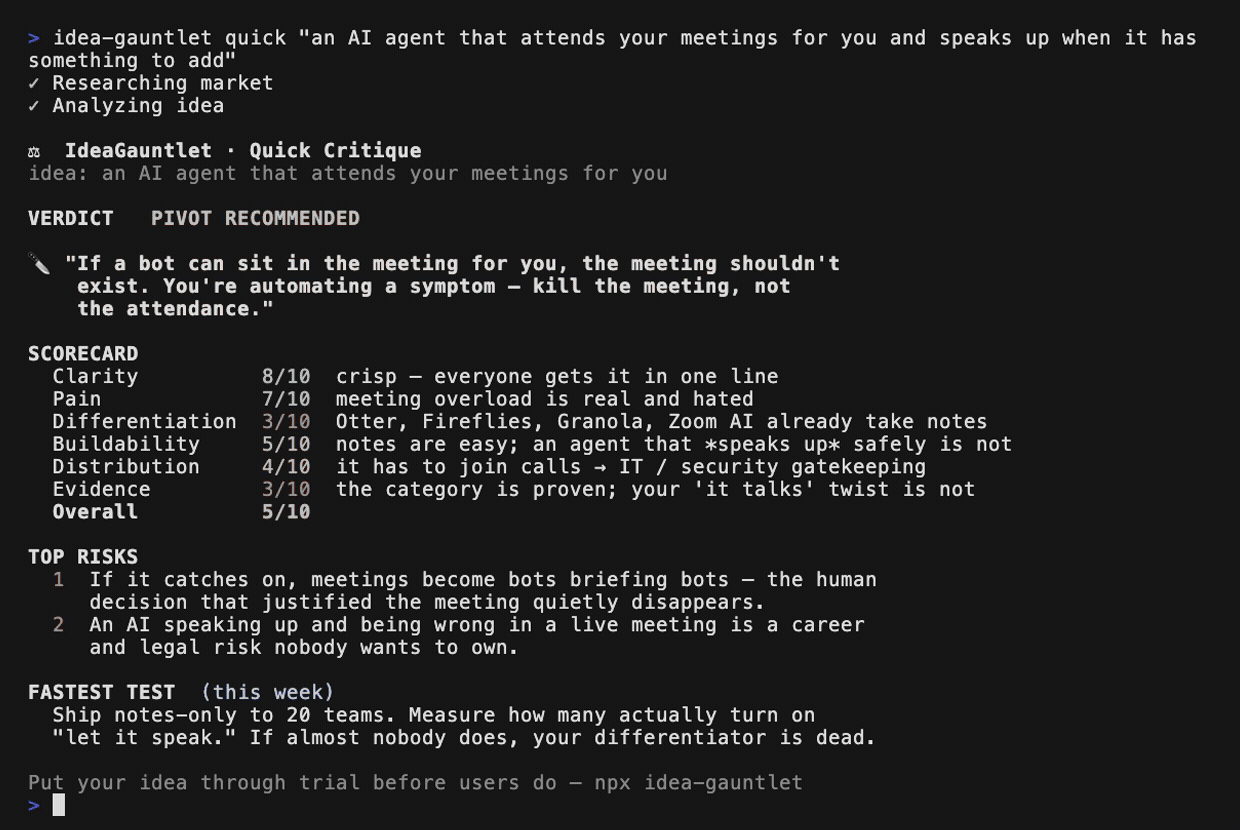
One command gives you a verdict, an evidence-backed scorecard, the risks that actually kill the idea, and the cheapest test that could disprove it this week.
npx idea-gauntlet quick "an AI agent that attends your meetings for you"
Install & Update
# Install
npm install -g idea-gauntlet

# Update to latest release
npm install -g idea-gauntlet@latest
On global install, IdeaGauntlet performs best-effort integration setup for detected Claude Code, Codex, Cursor, and MCP-compatible clients. All writes are non-destructive (never overwriting your files) and fully reversible via idea-gauntlet uninstall. The install downloads no browser and runs no network install; if postinstall was skipped (e.g. --ignore-scripts), run idea-gauntlet install yourself.
Try it
Inside Claude Code / Codex / Cursor
After installing, open your AI coding tool and ask:
Use IdeaGauntlet court mode to stress-test this idea:

A focus-room app for remote workers that pairs people into silent 50-minute work sessions.
No IdeaGauntlet API key is needed. The AI coding tool supplies the model and context. If postinstall did not detect your tool, run idea-gauntlet install later.
Important: Agent-native integrations execute workflows natively. They do not run the
idea-gauntletCLI first. If you typeidea-gauntlet court "..."in chat, the assistant treats it as analysis intent, not a shell command.
In the terminal — 30 seconds, no install
One command, nothing to install globally — just an API key:
ANTHROPIC_API_KEY=sk-ant-... npx idea-gauntlet quick "A focus-room app for remote workers"
Groq (GROQ_API_KEY=gsk_...), any OpenAI-compatible endpoint, or local Ollama (--ollama)
work too — see Provider setup.
Get a card you can actually post
Add --format card to any command to render the verdict as a self-contained
1200×630 image (OG / Twitter preview size) — verdict badge, overall score, score
radar, top risks, and the one-line brutal takeaway. Built to screenshot and share:
idea-gauntlet quick "Your idea" --format card -o idea.html # writes idea.card.html
Full details in Shareable Report Card.
See a real report
Two example reports for examples/IDEA.md, generated by IdeaGauntlet
itself (agent-native mode — the AI is the model):
examples/sample-quick-report.md— fast critiqueexamples/sample-court-report.md— full multi-role debate (steelman → skeptics → verdict)
A taste of the Quick verdict on that idea:
🔪 Focusmate has done exactly this since 2016 — "FocusRoom" as described is a feature, not a company; without a niche it can't defend, you're volunteering to fight a funded incumbent with a worse version of their product.
| Dimension | Score | Evidence | |---|---|---| | Differentiation | 2/10 | Focusmate already offers paired 50-min silent coworking since 2016; no stated wedge. | | Distribution | 3/10 | Two-sided cold-start: an empty room is worthless; paid ads can't fix it. | | Buildability | 8/10 | Matchmaking queue + timed video room — a fake-door + manual matching is enough to test. |
Core features
| Workflow | What it does | Use it when | Output |
|---|---:|---|---|
| Assumption ledger | Falsifiable assumptions, each with a kill threshold and the cheapest test that could disprove it | You want to know what to test first, before building | Ordered test plan, kill thresholds, days/cost to de-risk |
| Score calibration | Marks every score sourced or judgment, and discards citations not found in the retrieved research | You want to know which numbers are evidence and which are guesses | Basis per dimension, evidence ratio, flagged unverified citations |
| Quick critique | Fast adversarial review: top risks, assumptions, best/worst case, fastest test | You want a fast sanity check | Risks, assumptions, scores, validation test |
| Court mode | Structured multi-role debate with 7 specialist roles and judge verdict | The idea needs deeper critique | Role arguments, evidence audit, kill tests, scores, verdict |
| GTM Strategy | Distribution channel priority matrix, 100-customer playbook, launch milestones | You need an actionable distribution plan | Channel CAC/timeline, milestones, budget allocation |
| Competitive Intelligence | Competitor SWOT, 2D positioning map (X/Y), strategic windows & attack vectors | You want deep competitor mapping | Competitor profiles, positioning map, attack vectors |
| Revenue Model Explorer | Evaluates 12 revenue models with Y1/Y3 projections & tiered pricing | You want to find the optimal monetization model | Ranked models, fit scores, projections, pricing tiers |
| Founder-Market Fit | Evaluates domain expertise, network advantage & execution risk | You want an objective founder capability audit | Fit scorecard, unfair advantages, skill gaps, co-founder needs |
| Simulated User Interview | In-character customer discovery interview with realistic persona | You want to test real objections & willingness to pay | Two-way dialogue, latent needs, objection analysis, WTP |
| Pitch Deck Generator | 10-12 slide investor deck outline (YC, Sequoia, a16z frameworks) | You are preparing to pitch angels/VCs | Slide headlines, proof points, visual concepts, speaker notes |
| Idea Evolution Coach | Diagnoses core bottleneck & creates 3 structural pivot variants with score deltas | You want to improve or pivot a struggling idea | Pivot angles, projected score deltas, 48h smoke tests |
| Compliance Scanner | Audits legal, privacy & regulatory risks (GDPR, CCPA, HIPAA, AI Act) | You operate in regulated or data-sensitive markets | Risk severity, framework audit, pre-launch privacy checklist |
| Multi-Model Ensemble | Run idea through multiple LLM providers in parallel to expose bias | You want consensus scores without single-model bias | Aggregate scores, disagreement matrix, consensus verdict |
| Trend Monitoring | Re-research saved ideas to detect new competitors & niche shifts | You want to track market movements over time | Competitor delta, saturation shifts, emerging niches |
| Market sizing | Quantitative TAM, SAM, and SOM estimation with CAGR and economic assumptions | You want to size the market opportunity | TAM, SAM, SOM, CAGR, confidence, methodology |
| Unit economics | Financial viability assessment: CAC, LTV, LTV:CAC ratio, payback period, margins | You need to test unit economic feasibility | CAC/LTV estimates, ratios, payback, sustainability verdict |
| Anti-pattern audit | Stress-test against 10 classic startup traps (feature vs product, vitamin vs painkiller, etc.) | You want to spot structural failure traps early | Matched traps, risk severity, prevention advice |
| Synthetic users | Fictional personas with objections, switching costs, and interview questions | You want to prepare for real user research | Persona cards, objections, interview questions |
| MVP planning | Ruthlessly minimal validation plan with kill criteria and pivot options | You want to test, not debate | 14-day plan, experiments, kill criteria, pivot options |
| Idea comparison | Side-by-side scoring across 10 dimensions with per-idea kill tests | You need to choose what to validate | Comparison matrix, tradeoffs, recommendation |
| Batch mode | Run critique on multiple ideas from a file | You have several ideas to screen | Bulk reports with scores + verdicts |
| History & evolution | Save reports, track score deltas over time | You want to measure idea improvement | Saved reports, score deltas, evolution timeline |
| Interactive mode | REPL for iterative refinement, drill-down, mode switching | You want to refine an idea live | Re-runs, benchmark, diagrams, exports |
| HTML export | Styled dark-mode HTML report with radar chart + diagrams | You need shareable visual reports | Self-contained HTML page |
| Score benchmarking | Compare scores against a synthetic reference set of 50 idea archetypes | You want rough distributional context for your scores | Percentile ranking, similar archetypes |
Synthetic users are fictional — not research evidence. Scores are diagnostic signals, not predictions.
Two things IdeaGauntlet refuses to fake
1. It tells you which scores are evidence, and which are guesses
Most AI analysis tools present a retrieved fact and a confident guess in the same font. IdeaGauntlet separates them. Every scored dimension is labelled:
| Dimension | Score | Basis | Evidence |
|---|---|---|---|
| Differentiation | 2/10 | sourced | Focusmate has run paired 50-min sessions since 2016 |
| Distribution | 3/10 | judgment | Two-sided cold start — no source retrieved |
A model cannot mark its own work as sourced. It is asked to cite the sources it
used, and those citations are then checked against the research that was actually
retrieved. A citation that isn't there is stripped, flagged as unverified in the
report, and the dimension drops to judgment. Verification can only ever downgrade
a score's basis, never promote it.
Each report then states the ratio plainly:
Evidence-backed: 1/3 scored dimensions
●○○1 of 3 scored dimensions cite a source found in the research brief; 2 rest on model judgment alone. 1 claimed citation was not found in the brief and was not counted as evidence.
When no research is available at all, every dimension is judgment — the report
says so instead of implying grounding it doesn't have.
This applies to both quick and court. Court reaches its scores through a
seven-role debate rather than a single rubric call, but the judge's citations go
through exactly the same verification before any dimension is allowed to read as
evidence-backed.
2. It tells you what would prove the idea wrong, and what that costs
A verdict you can't act on is entertainment. assumptions turns the idea into a
falsification plan — what must be true, the number that declares it dead, and the
cheapest way to find out:
idea-gauntlet assumptions "A focus-room app for remote workers"
| # | Assumption | If false | Test | Timebox | Cost | Kill threshold | |---|---|---|---|---|---|---| | 1 | Remote workers will pay $10/mo rather than use a free timer | FATAL | Fake-door landing page + Stripe link | 3d | $50 | Fewer than 8 of 40 visitors leave an email | | 2 | A new room is never empty at peak hours | FATAL | Manually match 20 volunteers for a week | 7d | $0 | Under 60% of requested slots get matched | | 3 | IT teams will not block the video room | MINOR | 5 IT admin interviews | 10d | $0 | 3 of 5 admins say they would block it |
**Resolving every fatal assum
Truncated for display — read the full file on GitHub.
Related Skills
Agent-Reach
86.2kGive your AI agent eyes to see the entire internet. Read & search Twitter, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu — one CLI, zero API fees.
headroom
74.1kCompress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.
ruflo
73.5k🌊 The original agent harness. Deploy intelligent multi-player swarms, coordinate autonomous workflows, and build conversational AI systems. Features adaptive memory, self-learning intelligence, federation, vector RAG integration, and native Claude Code / Codex / Hermes and many more Integrated
CowAgent
47.2kOpen-source personal AI assistant & Agent Harness. Plans tasks, runs tools and skills, self-evolves with memory and knowledge. Multi-agent, multi-model, multi-channel. Lightweight, extensible, one-line install.

Languages
Trust signals
From repository metadata: license, adoption, age and documentation. Not a code audit — see the Safety scan above for what the skill file itself contains.